Think about the last time you tried to use information you found online. Maybe you were copying product prices from a website into a spreadsheet, or trying to make sense of a massive log file from your server. It was probably a chaotic mess of text, numbers, and code, right? This is where data parsing comes in.
In simple terms, data parsing is the process of taking that messy, unstructured data and turning it into a clean, organized format that a computer can actually understand and work with. It's like a translator, converting a jumbled block of text—like the raw HTML of a webpage—into something neat and tidy, such as a spreadsheet or a JSON file. This conversion is the absolute first step to making any raw data useful.
From Chaos to Clarity: An Introduction to Data Parsing
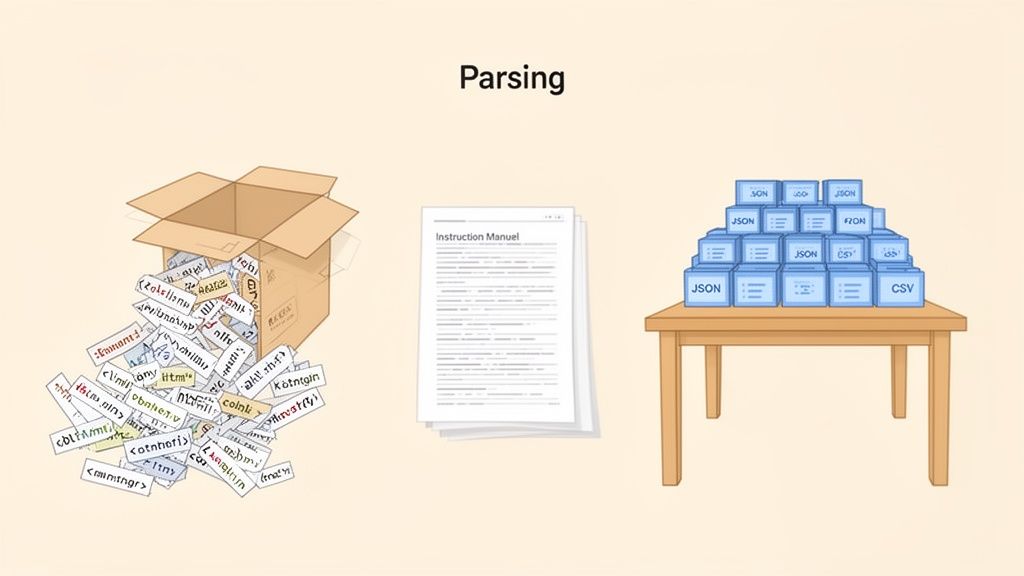
Here’s a good analogy: imagine you’ve just bought a giant, flat-pack bookshelf. You open the box and out spills a heap of screws, wooden panels, and mysterious plastic bits. Without the instruction manual, it’s just a pile of junk. In this scenario, that pile of parts is your raw data.
The act of parsing is like reading that manual. You're not creating new pieces; you’re just identifying each part, understanding its purpose, and figuring out how it all fits together. You're giving structure and meaning to what’s already there.
The Purpose of Parsing Data
The main goal of parsing is to make data understandable to a machine. A staggering 80% of all business information is locked away in unstructured formats like PDFs, emails, and random text on web pages. Without parsing, all that valuable knowledge is completely invisible to automated systems.
A parser follows a specific set of rules (its "grammar") to analyze a chunk of text and organize it logically. This is a fundamental process for tons of common tasks, including:
Web Scraping: Pulling specific product names, prices, and customer reviews from an e-commerce site’s HTML source code.
API Integration: Making sense of the JSON or XML data sent back from another service so you can use it in your own application.
Data Analytics: Turning raw, messy server log files into a structured table that you can actually analyze in a database.
Content Automation: Reading metadata from a Google Doc to automatically format and publish a new blog post.
Parsing is the essential bridge between chaotic, raw information and actionable insights. It translates the messy, human-readable language of the web into the clean, orderly language that software understands, powering everything from simple data entry to complex AI.
This transformation is about more than just tidying up data—it’s about unlocking its true potential. Once data is parsed, it can be sorted, searched, analyzed, and visualized. You can turn a confusing jumble of information into your most valuable asset. The entire world of data science, analytics, and business intelligence is built on this critical first step of bringing structure to chaos.
Here’s a quick look at how parsing transforms different types of raw data into ready-to-use formats.
Parsing Data At a Glance: From Raw to Ready
This table shows the journey from messy, raw data to a clean, structured output for a few common sources.
| Data Source | Raw Input (Before Parsing) | Parsing Goal | Structured Output (After Parsing) |
| --- | --- | --- | --- |
| E-commerce Page | Raw HTML code containing
tags with product info. | Extract product name, price, and customer rating. | JSON: {"name": "...", "price": 49.99, "rating": 4.5} |
| Server Log File | A long text file with lines like [timestamp] INFO: User [ID] logged in. | Isolate timestamp, log level, and user action for analysis. | CSV: timestamp,level,action
2024-10-26,INFO,login |
| Weather API | A single block of XML text with nested tags like and . | Pull out the current temperature and weather conditions. | A Python dictionary or similar data structure for app use. |
| Financial Report | A multi-page PDF document containing tables of revenue and expenses. | Extract numerical data from tables into a processable format. | An Excel spreadsheet with organized columns and rows. |
As you can see, the parser's job is to apply a set of rules to find the signal in the noise, turning what was once unusable into a valuable, structured asset.
The Parser's Toolkit: Common Methods and Techniques
Now that we know why we parse data, let's get into the how. Developers have a whole toolkit of methods to choose from, and each one is built for a different kind of challenge. Think of it like a chef picking the right knife—you wouldn't use a cleaver when you need a paring knife. It would be messy and inefficient. The same logic applies here.
This toolkit has everything from laser-precise pattern matchers to parsers that understand the entire structure of a document. Knowing which tool to grab for the job is the key to building fast, reliable data extraction pipelines. Let's unpack the most common methods, starting with one of the oldest and most powerful tools in the box.
Regular Expressions: The Precision Tool
Regular Expressions, or Regex for short, are super-powered search patterns. They’re designed to find and pull specific bits of text out of a larger, unstructured mess. Imagine a "find and replace" feature on steroids that can spot complex patterns like email addresses, phone numbers, or timestamps buried in a giant string of text.
For simple, predictable data—like log files where every line follows the exact same format—Regex is incredibly fast and effective. But it has a reputation for being brittle, especially when you point it at complex, nested structures like HTML. One tiny change to a website's layout can completely break a Regex pattern, which is why it’s not the best choice for scraping modern web pages.
DOM Parsing: The Structural Blueprint
When it comes to navigating the complex architecture of HTML and XML documents, developers turn to DOM Parsing. The Document Object Model (DOM) is a programming interface that treats a web page like a tree. Every piece of the page—a heading, a paragraph, a link, an image—is a "node" on this tree.
DOM parsing works by loading the whole document into memory and building out this tree structure. Once the tree is built, you can easily travel through it to find specific elements using their tags, classes, or IDs. This is perfect for web scraping because it understands the page’s layout, letting you reliably target data like "the price inside the div with the class 'product-price'."
This approach is the bread and butter of modern web scraping. At a platform like Scrappey, this means we can effortlessly handle JavaScript-heavy pages using headless browsers. The parser doesn't just grab static elements; it navigates dynamic content like the infinite scroll on Amazon or eBay product pages. Python is the dominant language in these dev stacks, used by 69.6% of developers, with libraries like BeautifulSoup and Selenium powering 39.1% of proxy-integrated parsing jobs. This ensures that geo-targeted data from major markets like the US and EU stays fresh and compliant. You can dive deeper into the analysis of the web scraping market's future demands.
Streaming Parsers: The Memory Saver
The biggest downside to DOM parsing? It needs to load the entire document into memory. That's usually fine for a standard web page, but what if you're dealing with a massive, multi-gigabyte XML file? Trying to load it all at once would crash most systems.
That's where Streaming Parsers, like SAX (Simple API for XML), save the day. Instead of building a full tree in memory, a streaming parser reads the file piece by piece, from top to bottom. It triggers events as it hits different elements (like an opening tag or a closing tag), letting you process data on the fly without hogging memory. This makes it exceptionally efficient for truly enormous datasets.
Dedicated Libraries: The Specialists
Finally, for common structured data formats like JSON, XML, and CSV, the best move is almost always to use a dedicated library. These libraries are highly optimized, dependable, and dead simple to use.
JSON Parsers: These are built into most modern programming languages. They can convert a JSON string into a native data structure (like a Python dictionary) with just a single line of code.
XML Parsers: Libraries like lxml in Python give you powerful tools for both DOM and streaming parsing of XML files.
CSV Parsers: These libraries handle all the little quirks of comma-separated values, like dealing with quotes, different delimiters, and headers.
These specialized tools are the go-to choice because they handle all the tricky edge cases and complexities of their formats right out of the box. You won't have to reinvent the wheel. If you're looking to get your hands dirty, check out our in-depth guide on using Regular Expressions for parsing.
Putting Parsing into Practice: A Web Scraping Example
Theory is great, but seeing data parsing in action is where it really clicks. Let’s walk through a real-world web scraping scenario to see how these pieces fit together. We'll use Python, the go-to language for most data tasks, along with its popular libraries, Requests for fetching web pages and BeautifulSoup for parsing them.
Our mission is simple: grab the product name, price, and customer rating from a fictional e-commerce page. This is the kind of thing that powers everything from price monitoring bots to market research tools. First things first, we need the raw material—the page's HTML.
Step 1: Fetching the Raw HTML
Before you can parse anything, you need the data. The Requests library makes this part a breeze. We just send an HTTP GET request to our target URL, and the server sends back the page's raw HTML content.
import requests
The URL of the fictional product page we want to scrape
url = 'http://example-ecommerce-site.com/product/widget-pro'
Send a GET request to the URL
response = requests.get(url)
Store the raw HTML content
html_content = response.text
print(html_content) Right now, html_content is just a huge, messy string of text and tags. It’s completely unstructured and a nightmare to work with, which makes it the perfect candidate for parsing.
Step 2: Parsing with BeautifulSoup
This is where the magic happens. We'll hand our raw HTML over to BeautifulSoup, which will chew through that jumbled string and spit out a structured object based on the Document Object Model (DOM). Think of it as creating an interactive map of the webpage that we can navigate with code.
from bs4 import BeautifulSoup
Create a BeautifulSoup object to parse the HTML
soup = BeautifulSoup(html_content, 'html.parser') With our soup object ready, we can start pinpointing the exact data we want. By inspecting the page's source code in a browser, we can find the specific HTML tags, classes, or IDs that hold the information we're after.
For this example, let's say the product info is marked up like this:
The name is in an
tag with the class product-title.
The price is in a tag with the ID product-price.
The rating is in a
tag with the class star-rating.
Using BeautifulSoup's intuitive find methods, we can pull this data out with just a few lines of code.
Extract the product name
product_name = soup.find('h1', class_='product-title').text.strip()
Extract the price
price_text = soup.find('span', id='product-price').text.strip()