C# web scraping is simply the process of using the C# programming language to pull public data from websites. It's a fantastic choice for building high-performance, scalable data extraction tools, especially if you're already working within an existing enterprise-level .C# web scraping is simply the process of using the C# programming language to pull public data from websites. It's a fantastic choice for building high-performance, scalable data extraction tools, especially if you're already working within an existing enterprise-level .NET application.
Why C# Is a Strong Choice for Web Scraping
While other languages often get the spotlight for web scraping, C# brings a unique set of advantages to the table. For developers in the Microsoft ecosystem, it’s a natural fit. Its strong typing, beefy performance, and excellent asynchronous features provide a rock-solid foundation for building data pipelines that just work.
The demand for web data is exploding. The global web scraping market was valued at USD 703.6 million in 2024 and is expected to climb to an incredible USD 3.52 billion by 2037. C# holds its own in this space, particularly in enterprise settings where .NET's raw performance is perfect for high-throughput jobs.
Key Strengths of Using C#
Picking C# for your scraping projects comes with some serious perks:
- Performance: C# is a compiled language, which means it often runs circles around interpreted languages like Python. This is a huge deal for large-scale or time-sensitive data jobs where speed is everything.
- Type Safety: The static typing in C# catches errors during compilation, not when your scraper is running live. This leads to more stable, maintainable code—a lifesaver for complex scraping logic.
- Asynchronous Support: C#'s built-in
async/awaitpattern is a game-changer for I/O-heavy tasks like making tons of web requests. You can build highly concurrent scrapers that don't just sit around waiting for responses. - Rich Ecosystem: The .NET framework offers a mature and massive ecosystem of libraries. You'll find powerful tools for HTTP requests, HTML parsing, and data handling that are all designed to play nicely together.
At its core, any C# web scraping operation follows a simple, three-step rhythm, as shown below.
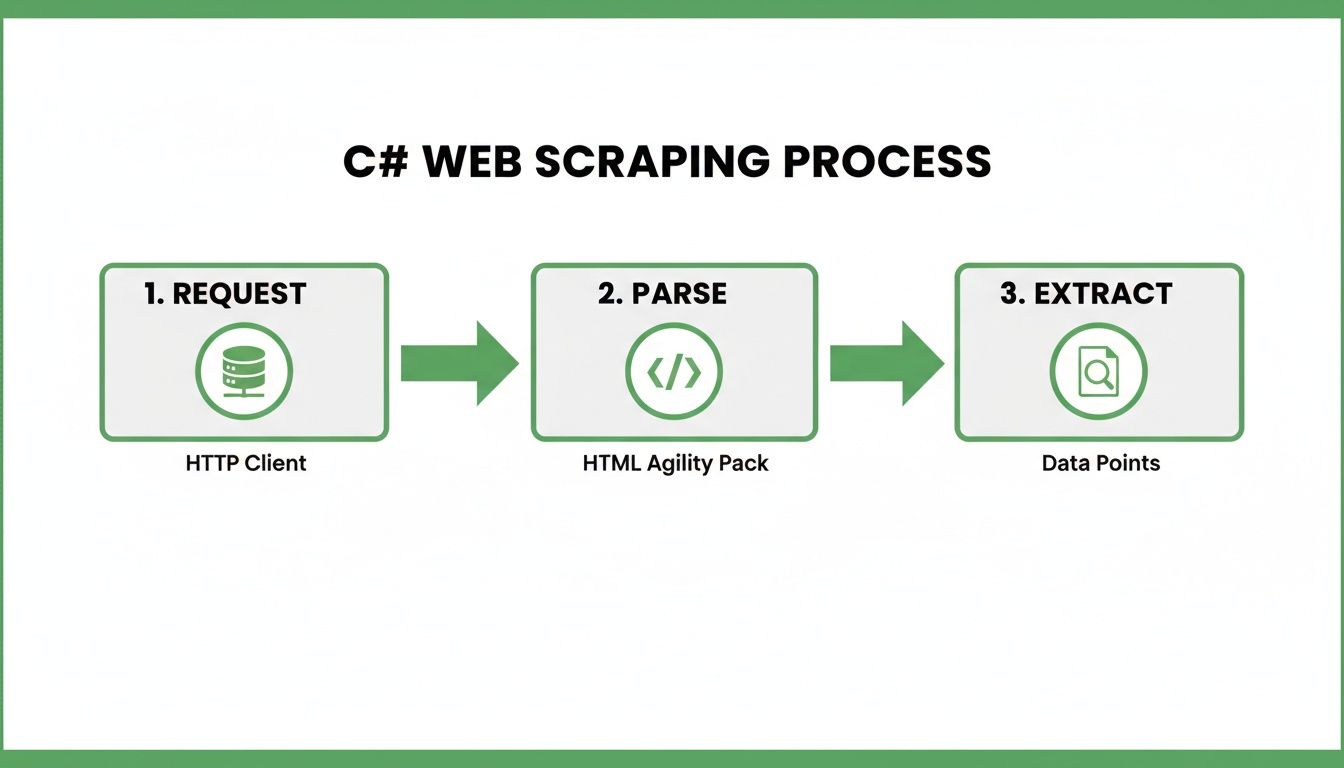
This flow is universal: your scraper sends a request, parses the HTML document it gets back, and then plucks out the specific data points you need.
Understanding the Core Components
No matter how complex your project gets, it all boils down to a few fundamental building blocks. You'll always start by making an HTTP request to a URL to fetch its raw HTML. From there, you need a way to parse that HTML, turning a long string of text into a structured object you can work with.
Finally, you'll use selectors to query this object and extract the exact pieces of information you're after.
Once you get a feel for this process, you can apply it to all sorts of tasks. It's the same foundation you'd use to scrape YouTube comments for a sentiment analysis project or gather product reviews from an e-commerce site.
Scraping Static Sites with HttpClient and HtmlAgilityPack
A huge chunk of the web is built on simple, static HTML. This makes it the perfect place to cut your teeth on your first C# web scraping project. We're going to lean on two absolute workhorses from the .NET world: HttpClient for grabbing the webpage and HtmlAgilityPack for making sense of it.
Think of HttpClient as the engine that fetches raw HTML from a server, handing it back to you as a giant string. But a raw string of HTML is a messy, unworkable blob. That’s where HtmlAgilityPack steps in. It takes that string and turns it into a structured object you can actually query, similar to how a browser constructs the Document Object Model (DOM).
Setting Up Your Scraping Environment
Before you write a single line of code, you need to get these two libraries into your C# project. The easiest way is through the NuGet Package Manager in Visual Studio, or you can just pop open your terminal and run these commands:
dotnet add package System.Net.Http dotnet add package HtmlAgilityPack
With those packages installed, you've got everything you need to request a page and parse its contents. The process is pretty straightforward: you'll fire up an HttpClient, send a GET request to your target URL, and then load the HTML response into an HtmlAgilityPack document.
Pro Tip: Always create a single, static instance of
HttpClientto use throughout your application's life. Spinning up a newHttpClientfor every single request is a classic rookie mistake that can lead to socket exhaustion—a nasty performance issue that’s a real headache to diagnose.
Fetching and Parsing HTML
Alright, let's pretend our mission is to scrape product names and prices from a basic e-commerce site. The very first thing we need is the page's HTML.
public async Task GetPageHtml(string url) { using (var client = new HttpClient()) { // Add a realistic User-Agent header client.DefaultRequestHeaders.UserAgent.ParseAdd("Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/108.0.0.0 Safari/537.36");
    var response = await client.GetAsync(url);
    response.EnsureSuccessStatusCode(); // Throws an exception if the request fails

    return await response.Content.ReadAsStringAsync();
}
} This little chunk of code sends a GET request and pulls the response body out as a string. See that User-Agent header? That one simple addition makes your request look like it’s coming from a normal web browser, which is often enough to get past the most basic anti-bot measures. For tougher targets, you can check out Scrappey's tools for making direct HTTP requests with custom headers and proxies.
Once you’ve got the raw HTML, you feed it into an HtmlDocument from HtmlAgilityPack.
var html = await GetPageHtml("https://example-ecommerce-site.com/products"); var htmlDoc = new HtmlAgilityPack.HtmlDocument(); htmlDoc.LoadHtml(html);
Just like that, your unstructured HTML is now a C# object you can navigate programmatically.
Extracting Data with Selectors
This is where HtmlAgilityPack really shines. It lets you pinpoint specific elements using XPath or CSS selectors. To figure out the right selectors, you’ll need to get friendly with your browser's developer tools. Just right-click the element you want to grab (like a product title) and hit "Inspect."
Let's imagine you inspect the page and find this HTML structure:
Premium Widgets
$19.99Standard Gadgets
$12.50We can easily target each product container and then pluck out the title and price from inside it. The SelectNodes method is your best friend here.
- Product Container Selector:
//div[contains(@class, 'product-card')] - Title Selector:
./h2[contains(@class, 'product-title')] - Price Selector:
./span[contains(@class, 'product-price')]
Putting it all together, we can loop through each product card and pull out the data we need.
var productNodes = htmlDoc.DocumentNode.SelectNodes("//div[contains(@class, 'product-card')]");
if (productNodes != null) { foreach (var node in productNodes) { var titleNode = node.SelectSingleNode(".//h2[contains(@class, 'product-title')]"); var priceNode = node.SelectSingleNode(".//span[contains(@class, 'product-price')]");
    var title = titleNode?.InnerText.Trim();
    var price = priceNode?.InnerText.Trim();

    Console.WriteLine($"Product: {title}, Price: {price}");
}
}
The InnerText property grabs the text content of an element, and calling .Trim() cleans up any annoying whitespace. This loop is the final step, efficiently turning a webpage into a clean, structured list of data. And that’s the fundamental workflow of static C# web scraping in a nutshell.
Tackling Dynamic JavaScript-Rendered Websites
The static web is pretty much a thing of the past. Modern websites are interactive experiences where content appears, changes, and updates without a single page reload. This magic is all powered by JavaScript, and it’s a huge roadblock for the simple HttpClient approach, which often just grabs an empty HTML shell.
If your scraper fetches a page and the data you need is nowhere to be found, it’s almost certainly because JavaScript loads it after the fact. To get around this, you need a tool that can act like a real user—something that can run JavaScript, wait for content to load, and even click around. This is where headless browsers enter the picture for C# web scraping.
Introducing Headless Browsers for C#
A headless browser is just a web browser without the graphical user interface. It can do everything a normal browser can—render HTML, execute JavaScript, handle cookies—but you control it all through code. For C# developers, two libraries really stand out for this job: Playwright and PuppeteerSharp.
Playwright, developed by Microsoft, is a modern and powerful choice. It gives you a clean API to control Chromium, Firefox, and WebKit, offering incredible flexibility. We're not just talking about getting the final HTML; we're talking about interacting with the page in a much more sophisticated way.
This approach is becoming critical. The global web scraping market is projected to hit USD 0.99 billion in 2025 and climb to USD 2.28 billion by 2030. C# tools like Playwright are already automating 70% of dynamic page scraping tasks, a capability that’s non-negotiable as interactive sites become the standard.
Setting Up Playwright for .NET
Getting Playwright running in your C# project is pretty straightforward. First, you'll need to grab the Microsoft.Playwright NuGet package.
dotnet add package Microsoft.Playwright
Once the package is added, you have to install the browser binaries that Playwright will control. The library comes with a simple command-line tool to handle this for you.
pwsh bin/Debug/net8.0/playwright.ps1 install
This command downloads the browser engines and gets them ready. With that out of the way, you're all set to start automating. For those still weighing their options, you might find a detailed comparison of Playwright and its predecessor, Selenium helpful.
Scraping a Page with Infinite Scroll
Let's tackle a classic dynamic scraping problem: an "infinite scroll" page where new products load as you scroll down. A simple HttpClient request would only ever see the first handful of items. With Playwright, however, we can simulate scrolling to trigger the JavaScript that loads more content.
Here’s what the code structure looks like.
using Microsoft.Playwright;
class Program { static async Task Main(string[] args) { using var playwright = await Playwright.CreateAsync(); await using var browser = await playwright.Chromium.LaunchAsync(new() { Headless = true }); var page = await browser.NewPageAsync();
    await page.GotoAsync("https://example.com/products-with-infinite-scroll");

    // Wait for the initial product containers to be visible
    await page.WaitForSelectorAsync(".product-item");

    // Simple loop to scroll down the page and load more items
    for (int i = 0; i < 5; i++) // Scroll 5 times to load more content
    {
        await page.EvaluateAsync("window.scrollTo(0, document.body.scrollHeight)");
        await page.WaitForTimeoutAsync(2000); // Give the page 2 seconds to load new items
    }

    var productTitles = await page.Locator(".product-title").AllInnerTextsAsync();

    foreach (var title in productTitles)
    {
        Console.WriteLine(title);
    }
}
} This script automates a few key actions:
- Launch Browser: It spins up a headless Chromium instance.
- Navigate: It goes to the target URL.
- Wait and Scroll: It waits for the first batch of content and then repeatedly scrolls to the bottom of the page, pausing to give the JavaScript time to fetch and render new items.
- Extract Data: Finally, it uses a
Locatorto grab all product titles and pull out their text.
Key Takeaway: The real power of headless browsers is their ability to execute JavaScript and wait for the results. Methods like
WaitForSelectorAsyncandWaitForTimeoutAsyncare your best friends for building reliable scrapers that don't break because they tried to access content before it even existed on the page.
By simulating user interactions like scrolling, clicking, and waiting, Playwright gives your C# web scrapers the muscle they need to pull data from virtually any modern website, no matter how complex its JavaScript is.
Navigating Anti-Scraping Defenses with Proxies
Sooner or later, you'll hit a wall. A website will spot your scraper's repetitive, machine-like behavior and block it cold. This isn't a failure; it's a rite of passage for any serious C# web scraping project. The trick is to build scrapers that are not just fast, but also smart and stealthy enough to blend in with normal user traffic.
This means moving beyond basic requests and adopting techniques that mimic how a real person browses. Simple but effective strategies include rotating your User-Agent header with each request and adding randomized delays. These small tweaks make your scraper appear less robotic and can dramatically reduce the chances of an instant block.
But the most powerful tool in your arsenal against IP-based blocking is a proxy server. By routing your requests through different proxies, you make each one look like it's coming from a unique user in a different location. This is the single most effective way to scale your scraping operations without getting shut down.
Understanding Different Proxy Types
Not all proxies are created equal, and picking the right one is crucial for your success. The proxy world is diverse, with each type offering a different balance of cost, speed, and anonymity. For a deep dive into the options, check out this comprehensive guide to the best proxy services.
Here’s a quick rundown of the most common types:
- Datacenter Proxies: These are the most common and affordable. They come from servers in data centers, offering high speeds, but their IP ranges are well-known, making them the easiest for websites to detect and block.
- Residential Proxies: These proxies route your traffic through real residential IP addresses assigned by internet service providers. They are much harder to detect, making them perfect for scraping heavily protected targets, though they come at a higher cost.
- Mobile Proxies: The premium option, these proxies use IP addresses from mobile carrier networks. They are extremely difficult for sites to block and are best for targets with the most stringent security.
C# developers have found that combining scrapers with rotating proxies—a technique with 39.1% adoption—boosts success rates to an impressive 95% against bot protections. This is especially vital for e-commerce teams tracking inventory across global sites, as it allows for consistent data collection without being easily flagged. You can explore more about these trends in this market analysis on web scraping software.
Integrating Proxies in C Sharp
Getting proxies working in your C# code is surprisingly straightforward. Whether you're using HttpClient for static sites or a headless browser like Playwright for dynamic ones, the core idea is the same: configure your request client to route traffic through the proxy server.
Let's see how to set up a proxy with HttpClient. You'll need to create a WebProxy instance and pass it to your HttpClientHandler.
var proxy = new WebProxy { Address = new Uri("http://your-proxy-address:port"), BypassProxyOnLocal = false, UseDefaultCredentials = false,
// If your proxy requires authentication
Credentials = new NetworkCredential(
    userName: "YOUR_USERNAME",
    password: "YOUR_PASSWORD"
)
};
var httpClientHandler = new HttpClientHandler { Proxy = proxy, };
using (var client = new HttpClient(handler: httpClientHandler, disposeHandler: true)) { var response = await client.GetStringAsync("https://target-website.com"); Console.WriteLine(response); }
This code tells the HttpClient to send all its requests through the specified proxy, including credentials if needed.
For Playwright, the setup is just as simple. You specify the proxy server settings when you launch the browser instance. This ensures every action the headless browser takes—from the initial page load to subsequent JavaScript-triggered requests—is routed through the proxy.
Crucial Takeaway: Manually managing a list of proxies, checking their health, and handling rotation logic can quickly become a complex project in itself. For anything beyond a simple test, it's far more efficient to use a proxy provider that offers a single rotating endpoint. You send your requests to one address, and the service handles all the IP rotation on the backend.
By strategically using proxies, you can transform a fragile script into a resilient data-gathering tool, ready to take on the defenses of the modern web.
Scaling Your Scraper with APIs and Best Practices
Getting a simple scraper up and running is one thing. Building one that can scale to thousands of pages and operate reliably is a completely different challenge. Once you move past hobby-level projects, the complexities of managing rotating proxies, solving CAPTCHAs, and handling headless browser farms can quickly become a full-time job. This is where the DIY approach starts to fall apart.
When you try to maintain all this infrastructure yourself, you’re constantly battling proxy blacklists, sophisticated browser fingerprinting, and anti-bot systems that change without warning. Your code gets bloated with complex retry logic and convoluted error handling, pulling your focus away from the real goal: getting the data.
Shifting to a Web Scraping API
For any serious C# web scraping project, a much smarter approach is to offload this heavy lifting to a specialized service. Instead of building and maintaining a complex evasion system from scratch, you can make a simple API call to a platform like Scrappey, which handles all the messy parts for you.
This shift means you can replace hundreds of lines of proxy management and browser automation code with a single, clean HTTP request. The API takes care of everything behind the scenes:
- Proxy Rotation: Automatically routes your requests through a pool of premium residential proxies to sidestep IP bans.
- Headless Browser Management: Renders JavaScript-heavy pages on its own powerful servers, so you don’t have to.
- CAPTCHA Solving: Seamlessly integrates solutions for the common challenges that would grind your scraper to a halt.
- Browser Fingerprinting: Manages user agents, headers, and other browser properties to make your requests look like they're coming from a real user.
This model lets you focus on parsing the final HTML you receive, not on the painful process of actually getting it.
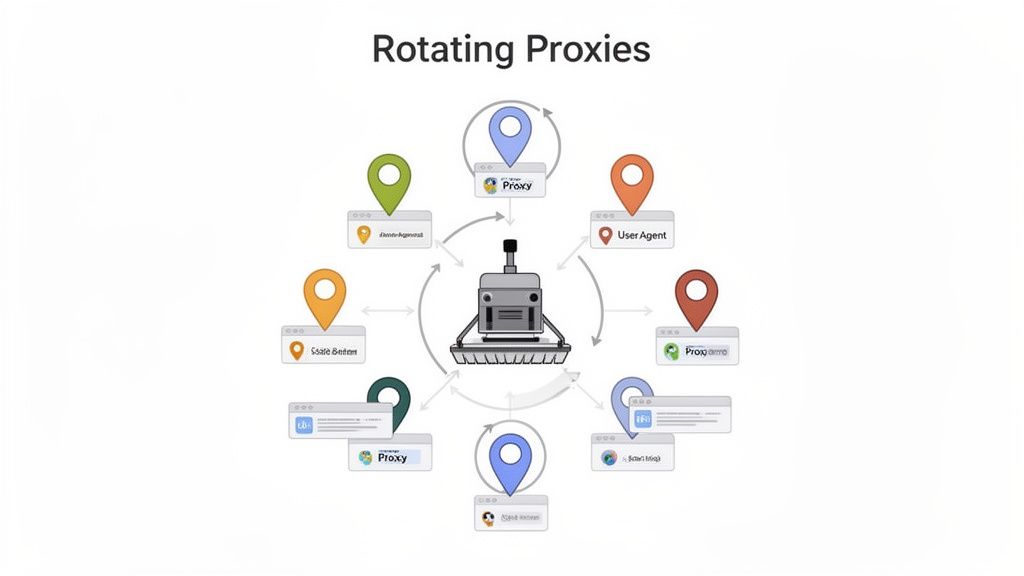
The diagram above gives you a glimpse into the kind of sophisticated proxy rotation system that a service like Scrappey manages for you. This is the kind of infrastructure that makes reliable, large-scale scraping possible without constant babysitting.
A Practical C Sharp Example with Scrappey
Let's look at just how much simpler this makes things. Imagine you need to scrape a dynamic e-commerce product page that's locked down tight. Instead of spinning up Playwright and wrestling with its configuration, you can just use good old HttpClient to call the Scrappey API.
All it takes is a simple POST request with your API key and the target URL.
using System.Net.Http; using System.Text; using System.Threading.Tasks; using System.Text.Json;
public class ScrappeyService { private static readonly HttpClient client = new HttpClient();
public async Task<string> ScrapeWithApi(string targetUrl)
{
    var apiKey = "YOUR_API_KEY";
    var apiUrl = "https://publisher.scrappey.com/api/v1?key=" + apiKey;

    var payload = new
    {
        cmd = "request.get",
        url = targetUrl,
        render = "js", // Tell the API to render JavaScript
        country = "us"  // Optional: specify a geographic location
    };

    var jsonPayload = JsonSerializer.Serialize(payload);
    var content = new StringContent(jsonPayload, Encoding.UTF8, "application/json");

    var response = await client.PostAsync(apiUrl, content);
    response.EnsureSuccessStatusCode();

    var responseBody = await response.Content.ReadAsStringAsync();
    // The responseBody is just the clean, final HTML from the page.
    // Now you can parse it with HtmlAgilityPack or AngleSharp.
    return responseBody;
}
}
With just this handful of C# lines, you've accomplished what would have required a massive amount of code to do manually with a headless browser and proxy setup. It’s a perfect example of the power of abstraction.
Key Insight: Using a scraping API fundamentally changes your role. You shift from being an infrastructure manager to a data consumer. Your primary responsibility becomes parsing the clean HTML you receive, dramatically accelerating development and improving reliability.
Essential Best Practices for Professional Scraping
No matter which approach you take, following a few key best practices will ensure your scraper is efficient, ethical, and easy to maintain. To truly scale your C# web scraper, thinking about the bigger picture is crucial. Digging into Software Architecture Best Practices for Scalable Apps can provide a solid foundation for building a robust and maintainable system.
Here are a few non-negotiable rules I stick to for any serious project:
Always Respect
robots.txt: This file is the website's way of telling you which pages are off-limits for bots. While it isn't legally binding, ignoring it is a surefire way to get your IP address blocked and is just plain bad practice.Cache Your Responses: Never scrape the same page twice if you can avoid it. Storing HTML responses in a local database or even just a file cache saves the target server from unnecessary load and makes your own development and testing cycles incredibly fast.
Identify Yourself in the User-Agent: Don't hide in the shadows. Set a custom User-Agent string that identifies your bot and ideally provides a way to contact you (e.g.,
MyCoolScraper/1.0 (+http://mycompany.com/bot.html)). This kind of transparency can prevent you from being blocked outright.Structure for Maintainability: Scrapers are notoriously brittle; websites change their layouts all the time. Design your code with a clear separation of concerns. Have different modules for fetching the page, parsing the data, and storing the results. This makes it far easier to update a single broken CSS selector without having to tear apart your entire application.
By pairing the power of a dedicated API with these professional standards, you can build C# web scraping solutions that are not only effective but also scalable, respectful, and built to last.
Common Questions About C# Web Scraping
Watch the video on YouTubeWhen you first dive into web scraping with C#, a few common questions always seem to pop up. Whether you're just getting your feet wet or you've hit a roadblock on a tricky project, getting solid answers can save you a ton of headaches. This section tackles the most frequent queries developers have, giving you practical advice to help you build smarter, more resilient scrapers.
We'll clear up the confusion around everything from choosing the right language to dealing with those pesky anti-bot measures. Once you've got these fundamentals down, you'll be ready to take on much bigger data extraction challenges.
Is C# a Good Choice for Web Scraping Compared to Python?
Absolutely. While Python gets a lot of the limelight with its massive community and scraping-specific libraries, C# is a powerhouse, especially for performance-heavy and enterprise-grade scraping. Its strong typing is a huge plus, catching potential errors at compile time before they have a chance to crash a long-running job.
On top of that, C#'s built-in async/await features are a perfect match for juggling tons of web requests at once, which is a must for any serious scraping operation. If you're already in the .NET world, sticking with C# is a no-brainer—it integrates beautifully with your existing apps and data pipelines.
How Do I Handle Websites That Block My Scraper?
Sooner or later, you're going to get blocked. It’s practically a rite of passage in web scraping. The trick is to make your scraper act less like an automated script and more like a real person browsing the web. This isn't about one single fix; it's about a layered defense.
Here’s where to start:
- Set a Realistic User-Agent: First thing's first, make sure your HTTP requests include a User-Agent header that looks like it's coming from a popular, modern browser.
- Implement Rate Limiting: Don't hammer the server. A real user doesn't click a hundred links a second, and neither should your scraper. Add random, natural-feeling delays between your requests.
- Use Rotating Proxies: When you're serious about not getting blocked, you need to route your requests through a pool of rotating proxies. Residential proxies are the gold standard here, making your traffic look like it’s coming from countless real users. This makes it incredibly difficult for a website to tell your scraper apart from its regular visitors.
For any project at scale, trying to manage proxies, headers, and retries yourself is a massive time sink. This is exactly why services like Scrappey exist—they handle all that complexity for you, giving you a much more reliable and efficient way to get the data you need.
What Is the Best Way to Store Scraped Data in C#?
The "best" way to store your data really comes down to your project's size and what you plan to do with the information. There's no one-size-fits-all answer, but a few standard approaches cover most situations.
For quick, one-off jobs, just dumping the data into a flat file is perfectly fine. A library like CsvHelper makes writing to a CSV file incredibly easy, and the built-in System.Text.Json is fantastic for serializing your C# objects into a JSON file.
But when you're working with larger, structured datasets that you'll need to query later, a real database is the only way to go. The industry-standard approach is using Entity Framework Core to map your C# objects to a database like SQL Server, SQLite, or PostgreSQL. It's robust, ensures data integrity, and makes it simple to plug your data into other business tools or analytics platforms.
Is Web Scraping Legal?
This is a big one, and the answer is nuanced: it depends on what you scrape and how you use it. In general, scraping publicly available information is legal.
However, it's on you to operate within ethical and legal lines. That means staying away from personal data to comply with privacy laws like GDPR, not touching copyrighted content, and always respecting a website's Terms of Service. A great first step is to always check a site's robots.txt file and follow its rules. Most importantly, scrape responsibly and don't bring a server to its knees. If you're ever in doubt, talking to a legal professional is the smartest move you can make.
Ready to skip the headaches of proxy management and CAPTCHA solving? Scrappey handles the entire complex backend, so you can focus on the data, not the roadblocks. Get started today with a simple API call and see how easy large-scale web scraping can be. Learn more at https://scrappey.com.